 Model card on Hugging Face


Decision-1 is Worthify's model for scoring the choices an application supplies. We built it on Google's Gemma 4, with further training on decisions about routing, evidence, and procedures.
Starting with Gemma 4
Workflow inputs range from short requests to dense policies and tickets with only half the story. Google's Gemma 4 brings broad language and reasoning capabilities to that work, giving our training a foundation to build on. We can focus on the judgment the workflow needs.
The open weights make that foundation practical to build on. Google releases Gemma 4 under Apache 2.0, so we can train the model itself, run it on infrastructure we choose, and share the resulting weights. A team can take the model into its own system and adapt it as its work changes.
For Decision-1, we started with the instruction-tuned Gemma 4 12B checkpoint and trained it to weigh a supplied set of answers against the available context.
Reading choice scores from Gemma's logits
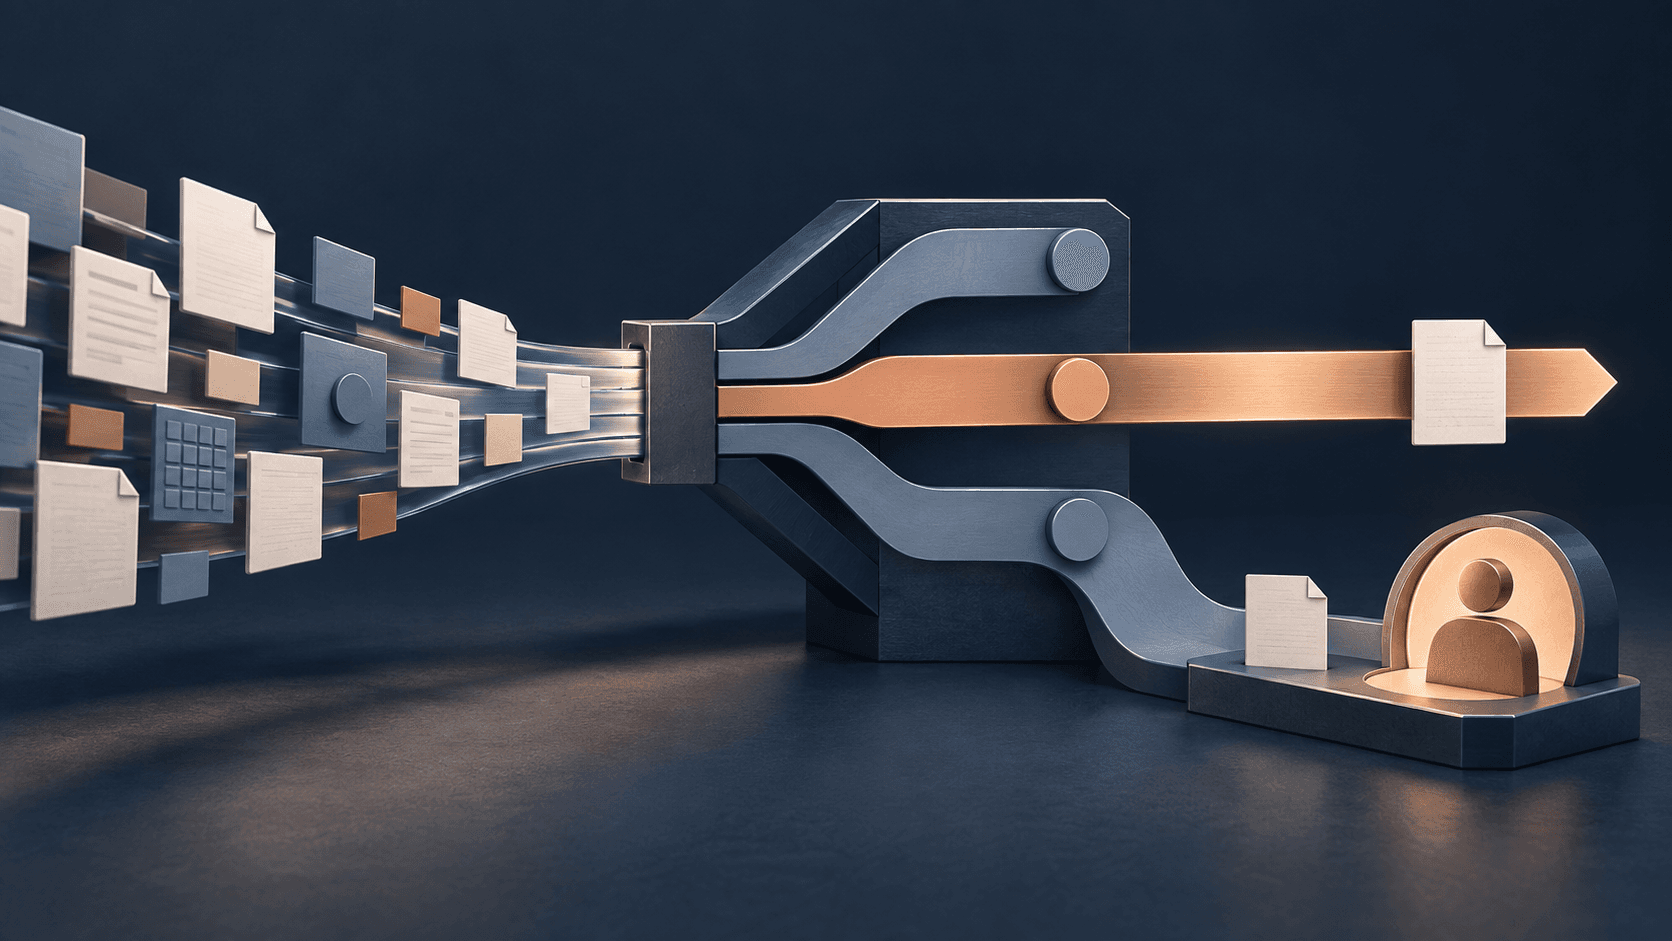
At the end of Gemma's text transformer, the vocabulary head projects the final hidden state into next-token logits. A generative application uses those scores to sample a token, append it to the sequence, and repeat until the answer is complete. The application then has text to interpret.
The OpenJev pattern takes the option scores directly. Decision-1 retains Gemma's native vocabulary head and replaces the answer-generation path with a restricted choice readout. It gathers the logits for the offered answers and returns scores the application can use. The head's projection matrix remains in the model.
- Decision prompt
State + question + described options, encoded with Gemma’s chat template.
- Gemma 4 text transformer
Computes the hidden state at the final prompt position.
- Native vocabulary head
Retained. Produces next-token logits over the vocabulary.
Decision-1 direct readout
Gather A … P → menu softmax
One forward pass returns original option IDs and scores over the offered choices. The application uses argmax or a review rule.
The generative output path samples, appends, and repeats to produce answer text or JSON. Direct readout takes the offered token scores before that decoding loop.
L = −log p(gold choice)
Gradients update the native head and all text-transformer weights.
Option descriptions and answer slots
The prompt pairs each option description with a single-token letter, from A through P. Those letters are temporary slots: A might mean billing in one request and missing evidence in another. The descriptions carry the meaning. The scorer keeps the original option IDs and maps the slot scores back to them.
After one forward pass, we read the logits at the final prompt position and gather only the declared answer tokens. For a menu of n choices, that gives a vector of n scores. Softmax normalizes across that vector, and the application can take its argmax or apply a review rule. Scoring ends without sampling an answer token or parsing generated JSON.
The scores depend on the menu: an omitted answer cannot win, and changing the alternatives changes the normalization. They express preference among the offered choices and do not provide calibrated confidence that a claim is true. The direct scorer shows the token checks, final-position readout, and slot selection.
Full-weight decision training
We trained the full text model on 35,210 decision examples. Each one contains context, a question, descriptions of the available choices, and the correct answer. During training, we update the model's weights to favor that answer over the other offered choices.
The loss is cross-entropy over the offered slots. If ℓ is the vocabulary-logit vector, tᵢ is the token ID for choice i, and y is the correct slot, the objective is:
zᵢ = ℓ[tᵢ]
pᵢ = exp(zᵢ) / ∑ⱼ₌₁ⁿ exp(zⱼ)
L = −log pᵧ
The denominator includes only the choices in that row. When a batch contains menus of different lengths, the trainer masks the unused slots so they contribute neither to the loss nor to the predicted choice. Gradients flow back through the retained vocabulary head and the transformer. Our full-weight run trained all 11.9 billion text parameters.
We shuffle the choices during training, so the correct slot moves with its description. That reduces the opportunity to learn a fixed answer position. We mix routing requests, evidence questions, procedures, and uncertainty in the same format, encouraging the model to attend to the supplied context and descriptions across different decision tasks.
OpenJev supplies the direct-readout approach; Worthify's contribution here is the Gemma decision post-training. That training is part of the released weights. A team can use the scorer directly or later train a task LoRA for its own work using the same restricted-choice objective.
We kept training, checkpoint selection, and testing separate. Validation selected the checkpoint; the held-out test came afterward. The model card records the data, training run, and evaluation setup.
Reviewing a security finding
Say you're reviewing whether a security finding can be closed. The ticket says a patch was approved. You look for a record that it was installed and a scan showing the issue was resolved. Those attachments aren't there.
You offer the scorer three answers: ready to close, missing evidence, or needs review. Missing evidence is the intended answer here. The approval lets the work proceed; it leaves the question of completion open. When the installation record and clean scan arrive, ready to close becomes supportable.
A scorer could help the application send an incomplete packet back for the missing records and bring a conflicting one to an analyst. In a review workflow, test whether it makes those handoffs correctly. The person still owns closure. The scores compare the offered answers; they do not provide calibrated confidence that a claim is true.
Held-out intent routing / 768 cases
Decision-1 led the routing comparison
To measure what the training added, we compared Decision-1 with the Gemma starting point and an earlier task LoRA on held-out intent-routing requests. Decision-1 led both.
| Model | Routing macro-F1 |
|---|---|
| Frozen Gemma 4 12B | 62.21% |
| Earlier task LoRA | 66.38% |
| Decision-1 | 67.29% |
That's a 5.08 percentage-point gain over frozen Gemma and a 0.91-point lead over the earlier task LoRA. This is one supplied-choice routing task from one completed training seed. The analyst example above describes a possible use; this table is the measured result.
Evaluation details
All three models used the same BF16 scorer, in batches of four, on one A100. Macro-F1 averages label-level F1 scores. It includes 151 offered labels; 46 had no gold example in the test sample, and 512 rows used none_of_above as the gold label. The pinned model card contains the complete seven-family evaluation and separate task-adapter studies.
Using Decision-1 in your workflow
Start with a question your team already answers and write down what each allowed answer means. Include a review option when the records may be incomplete or conflicting. Then compare the model's choices with human-labeled cases, paying attention to the mistakes that would send work to the wrong place.
You can try the published model directly, without a task adapter or labeled examples in the request. If the task needs further training, the LoRA recipe provides that path. Keep test cases out of tuning and checkpoint selection.
Code example: score a request
This short example asks the scorer to label a contract paragraph. The intended label is deliverable. The scoring request has no gold label. Download the JSONL row shown below.
{
  "id": "acquisition-labeling-exercise-1",
  "state": "The contractor shall submit an asset inventory report to the contracting officer.",
  "question": "Which label best describes this excerpt?",
  "options": [
    {
      "id": "deliverable",
      "description": "A work product the contractor must provide."
    },
    {
      "id": "security_requirement",
      "description": "A required security control or practice."
    },
    {
      "id": "period_of_performance",
      "description": "The contract performance dates or duration."
    },
    {
      "id": "review",
      "description": "Needs human review because the excerpt is ambiguous or outside these labels."
    }
  ]
}
You'll need Python and a CUDA GPU with enough memory to load the 12B model in NF4. Clone the pinned scorer and install its dependencies. The dependency group is called train; this command loads no adapter and updates no weights.
git clone https://github.com/Worthify-AI/worthify-decision-1.git
cd worthify-decision-1
git checkout c66740244446c9cb0adce88a37efb8e98913ed71
python -m venv .venv
.venv/bin/python -m pip install -e '.[train]'
curl -fsSL https://worthify.ai/examples/decision-1-zero-shot.jsonl -o decisions.jsonl

CUDA_VISIBLE_DEVICES=0 .venv/bin/worthify-lora score \
  --model Worthify/Decision-1 \
  --revision cb54dcd238da782a21035bb39a1b057d743af832 \
  --quantization nf4 --max-tokens 2048 \
  --input decisions.jsonl --output scores.jsonl
The scorer writes one JSON result per input row. Print the highest-scoring option's ID and the conditional scores, then compare the selected ID with deliverable:
.venv/bin/python - <<'PY'
import json

with open("scores.jsonl") as file:
    result = json.loads(file.readline())
best = max(range(len(result["option_ids"])),
           key=lambda i: result["option_logits"][i])
print("Selected ID:", result["option_ids"][best])
print("Conditional scores:", dict(zip(
    result["option_ids"], result["probabilities"])))
PY
Use a new output filename for each run; the scorer will not overwrite an existing file. This NF4 example differs from the BF16 benchmark setup. Scores are normalized across the menu and are not calibrated confidence. See the pinned source for the runtime contract.
Judge the scorer by how well it helps your application route work, keep missing evidence visible, and bring unresolved cases to someone who can review them.